DevOps Transformation
SSH deploys + rollback terror → <10 min pipelines, <30s rollback, deploy-related incidents near zero.
Reported engagement figures. See the results section for measurement context and limitations.
- Role
- Lead Platform Engineer
- Context
- SaaS / Platform
- Duration
- 4 months
- Team
- 2 platform engineers (me + 1) supporting 25 developers
Why they called
Twenty-five developers were deploying by SSH into a bastion, pulling code and restarting services by hand. A release took two to three hours, one in five had to be rolled back, and a rollback itself took 30 to 60 minutes. Infrastructure existed only in the console. The team shipped once every two weeks and spent much of the time in between recovering from the last deploy.
Tech stack
- GitHub Actions
- Terraform
- AWS ECS
- CodeDeploy
- Docker
- ECR
- S3
- DynamoDB
- CloudWatch
- Slack Webhooks


Business problem and production context.
Business problem
Engineering team of 25+ developers was deploying manually via SSH. Release cycles took 2-3 hours with frequent rollbacks. No automated testing. Bugs were caught in production. Infrastructure was provisioned via ClickOps in the AWS console with no version control or reproducibility.
Architecture decision
Designed and implemented a complete CI/CD pipeline using GitHub Actions with reusable composite workflows. Migrated all infrastructure to Terraform with remote state in S3 + DynamoDB locking. Implemented blue-green deployments on ECS with automatic rollback on health check failures. Set up multi-stage environments (dev/staging/prod) with promotion gates. Added automated testing (unit, integration, E2E) with 95%+ coverage requirements enforced in CI.
Before and after.
Figures below come from the engagement account. Where no measurement source or period is provided, they are labelled reported. Workload scale, targets and engagement outcomes are different measures; past results are not a forecast for another system.
Push-to-deploy pipelines with blue-green releases on ECS that developers can roll back themselves.
The build, release and Terraform state path. The load balancer behind the blue-green switch, networking and the per-service task definitions are not shown.
Main components only; supporting services are left out.
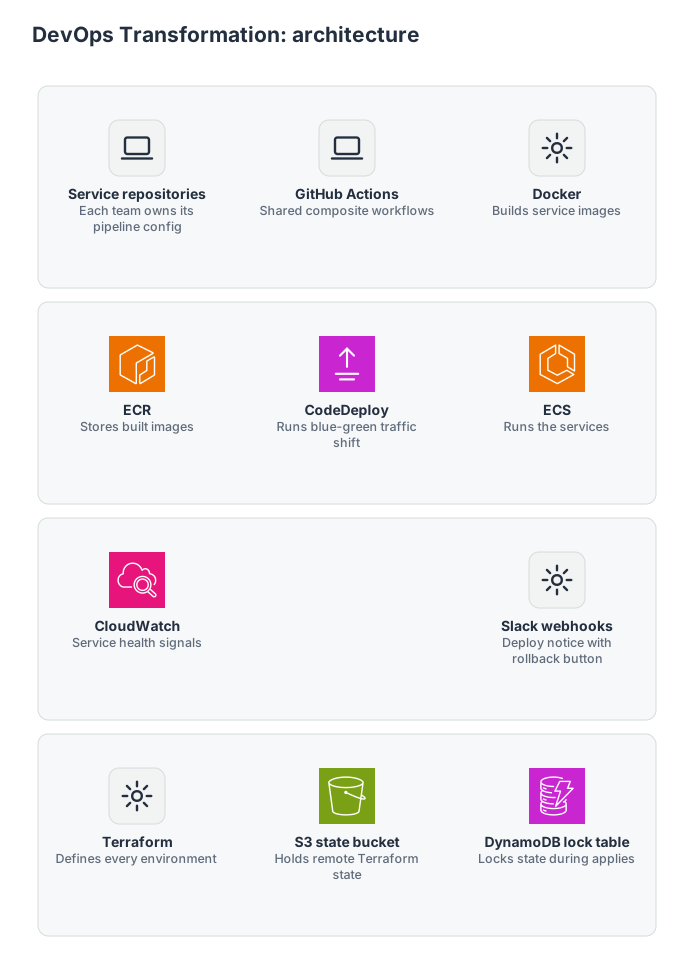
Build and test
Service repositories
Each team owns its pipeline config
GitHub Actions
Shared composite workflows
Docker
Builds service images
Release

ECR
Stores built images

CodeDeploy
Runs blue-green traffic shift

ECS
Runs the services
Feedback

CloudWatch
Service health signals
Slack webhooks
Deploy notice with rollback button
Infrastructure as code
Terraform
Defines every environment

S3 state bucket
Holds remote Terraform state

DynamoDB lock table
Locks state during applies
How it works, step by step
- 1A push triggers the repo's shared composite workflow in GitHub Actions, which runs the tests and stops if coverage is under the gate.
- 2The workflow builds a Docker image and pushes it to ECR.
- 3Dev and staging deploy automatically, staging also runs full-journey tests, and production waits for manual approval.
- 4CodeDeploy shifts the ECS service from blue to green and rolls back on its own if health checks fail.
- 5Slack announces each production deploy with a rollback button the developer can press without a platform engineer.
Guardrails
- Pull requests below the coverage threshold are blocked in CI
- Production deploys need manual approval
- Failed health checks trigger an automatic rollback
- Pipelines deploy by assuming a dedicated AWS deploy role
- All infrastructure, including resources imported from the console, changes only through Terraform with locked remote state
Considered and not used
- Canary deploys: Blue-green gave instant rollback while the team was new to automated deploys.
- Jenkins: GitHub Actions had native repo integration and less to maintain.
- AWS CDK: Terraform kept teams consistent and HCL was easier for junior engineers; CDK deferred.
- Monorepo CI: Polyrepo with shared composite actions let each team own its pipeline.
My part of the work, separate from the team's.
The team behind the engagement is in the facts row above. These are the parts I was responsible for, and the artifacts that show the work.
Owned scope
- CI/CD, deployment safety, and rollback improvements for teams moving beyond manual releases
- Release health signals and ownership boundaries for production changes
- IaC and automation paths that reduced risky human coordination
Evidence artifacts
What would fail first?
Every project has constraints. The useful work is naming them early enough that rollback, cost, and ownership are designed before an incident.
Manual releases
Release confidence was limited by handoffs, manual checks, and unclear rollback.
Service ownership
Deployment automation needed owners who understood how to respond when a change failed.
Environment drift
CI/CD reliability depended on consistent environments and predictable configuration.
Trade-offs accepted on purpose.
Production risks and how they were controlled.
Small steps, visible changes, fewer surprises.
- 01
Documented existing deployment process: SSH into bastion → pull latest code → restart services → manually verify. Average deploy: 2-3 hours with 1 in 5 requiring rollback.
- 02
Migrated all 12 repositories to GitHub Actions with reusable composite workflows: test → build → push to ECR → deploy to ECS with CodeDeploy blue-green.
- 03
Converted all infrastructure from ClickOps to Terraform with remote state in S3 + DynamoDB locking. Ran `terraform import` on 180+ existing resources over 3 weeks.
- 04
Built multi-stage promotion pipeline: feature branch → dev (auto-deploy) → staging (auto-deploy + E2E tests) → prod (manual approval + blue-green + Slack notification).
- 05
Added test coverage enforcement in CI. PRs below 95% coverage automatically blocked. Wrote 400+ integration tests as bootstrap to get the team past the initial hurdle.
What the team runs now.
The point of the work is what the client's own engineers can change and operate without me.
- The GitHub Actions pipelines and the shared composite workflows across all 12 repositories. Each team owns its own pipeline configuration.
- Terraform for every environment, with remote state and locking, so no change goes through the console any more.
- Blue-green deploys with a one-click rollback from Slack, run by the developers themselves with no platform engineer in the loop.
- The 95% coverage gate in CI, kept green by the team after the two weeks of paired test writing that got them past it.
What carries over to your system.
- Terraform import of 180 existing resources was the hardest part. Some resources had undocumented dependencies. We spent 3 weeks on import alone, but it was non-negotiable for preventing drift.
- Test coverage enforcement initially caused developer pushback. We addressed it by pair-programming test writing for 2 weeks, plus creating test utilities that made common patterns one-liners.
- Slack deploy notifications with one-click rollback buttons transformed team confidence. Knowing you can undo in 30 seconds made everyone more willing to deploy frequently.
Rollback path
Rollback was treated as part of architecture: deployment strategy, state changes, owners, and verification.
Cost considerations
The main cost benefit was lower incident/release drag, plus cleaner non-production environment usage.
Observability notes
Signals included deploy frequency, failure rate, rollback time, environment health, and customer-impact alarms.
Further reading
Services built on this work
Have a similar production problem?
Send the current architecture, bill concern, deployment pain, or GenAI reliability issue. I will help you find the first real bottleneck.
 Request the reliability audit