Serverless and Event-Driven Platform Build
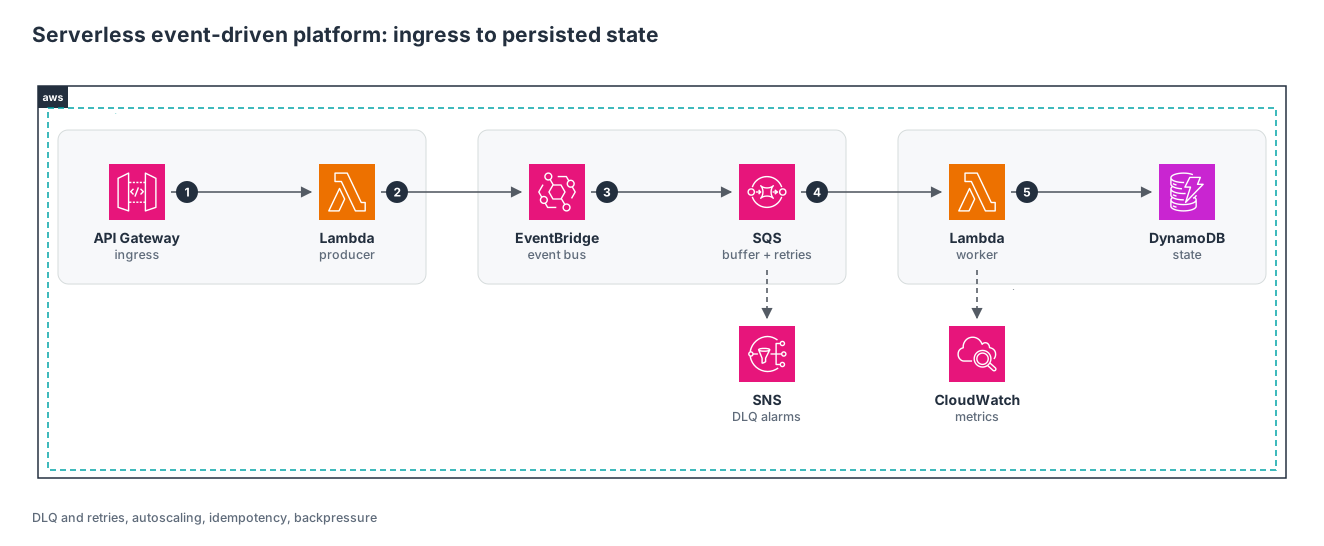
A build of an event-driven platform on Lambda, SQS, EventBridge, Step Functions and DynamoDB, delivered as infrastructure-as-code modules with retries, dead-letter queues, alarms, a rollback runbook and a handover to your team.
You need the system to handle real traffic without hiring a large operations team or defaulting to Kubernetes too early.
 Request the reliability audit
Best fit
Teams that need scale without carrying a heavy operations burden.
Timeline
4-10 weeks
Proof frame
NDA-safe examples can be discussed with sanitized or NDA-safe detail.
Symptoms first, architecture second.
The useful work starts by naming what is hurting, what can be measured, and what can be changed safely this week.
What you may be seeing
- Synchronous calls are creating cascading failures
- Workers, retries, and DLQs are missing or inconsistent
- Kubernetes is being considered by default
- Traffic spikes require manual babysitting
How I find the cause
- API Gateway, Lambda, SQS, EventBridge, Step Functions
- DynamoDB access patterns
- DLQ design, retries, idempotency, alarms, and IaC
- blast radius and fallback paths
The output has to survive handoff.
The point is not a prettier diagram. The point is a plan that names service boundaries, owners, rollback, cost drivers, and what gets observed.
I will not suggest Kubernetes when Lambda, SQS, and Step Functions solve the problem with less operational load.
What you get
- - event flow and service boundaries
- - IaC modules
- - deployment and rollback runbook
- - observability baseline
- - operational handoff
What to bring
- - traffic patterns
- - critical workflows
- - current deployment flow
The method behind this service, written up.
Case studies behind this service.
Event-Driven Commerce Migration
Major QSR e-commerce platform (Thailand) · Imaginato
Peak-hour monolith failures + inflated EC2 → 5M+ orders/mo, P99 <200ms, ~30% infra reduction.
- Orders/Mo
- 5M+
- Latency
- <200ms
- Cost Red.
- 30%
Real-Time Processing
AppGambit · AWS consulting delivery
Hour-long audit lag vs compliance → <5s pipeline, 1M+ req/min, ES search <100ms at billions of rows.
- Throughput
- 1M+/min
- Query Time
- <100ms
- Uptime
- 99.99%
SaaS Platform Arch
ProdigyBuild
ClickOps + slow environments blocking ship → serverless API with a 99.9% availability target, 40% AWS cut, envs in minutes.
- Availability target
- 99.9%
- Cost Red.
- 40%
- Dev Velocity
- +60%
Questions before you book.
When is serverless the wrong answer?
When workload shape, latency profile, runtime limits, team skills, or stateful processing make containers simpler and safer.
Do you include observability and rollback?
Yes. Event-driven work is incomplete without retries, DLQs, idempotency, alarms, and a rollback/runbook story.