AWS CDK CodeDeploy pipeline for EC2 Auto Scaling behind an ALB, without 502s on deploy
Build an AWS CDK CodeDeploy pipeline for EC2 Auto Scaling behind an ALB, with the health check, deregistration and rollback settings that stop 502s on deploy.
On this page
AWS CodeDeploy reports a successful deployment, and users behind the Application Load Balancer (ALB) still get 502 errors. This guide is for engineers who build an AWS Cloud Development Kit (AWS CDK) pipeline from AWS CodePipeline through AWS CodeBuild to CodeDeploy on Amazon EC2 Auto Scaling, and need it to hold up under real load. You get the architecture, the CDK wiring between the target group and the deployment group, four failure modes with their fixes, and a cost estimate for a five-instance fleet.
Who this guide is for
You are a backend or DevOps engineer already comfortable with CDK and AWS. You have shipped a few stacks. You know what an ALB is. You want to wire CodePipeline to CodeBuild to CodeDeploy to an Auto Scaling group (ASG) in a way that holds up under load and handles rollbacks.
It is also for teams who have been burnt by container migrations. Amazon Elastic Container Service (Amazon ECS) may not fit yet, the app may have stateful assumptions, or the organisation may not be ready. In that case the EC2-based deployments need to be production-grade for the long term.
Why a green deploy can still serve 502s
With CodeDeploy, Auto Scaling and an ALB, the compute layer is the easy part.
The hard part is the coordination layer. CodeDeploy has its own definition of healthy. The ALB has its own. The ASG has its own.
All three have to agree. If they do not, the deploy is technically successful while your users get 502s.
The failure looks like this. The pipeline is green and Amazon CloudWatch shows the EC2 instances running. Meanwhile the ALB is draining targets, because the health check path returns 404 during the ApplicationStart lifecycle phase, while the new app version is still starting up.
CodeDeploy does not know. The ASG does not know. The ALB removes the instances from rotation and moves on.
Rollback has its own gap. It works until a lifecycle policy on your Amazon S3 artifact bucket deletes the previous revision.
CodeDeploy then reports that it is rolling back, and fails because there is nothing to roll back to. Check this before an incident, when you still have time to fix it.
The operational glue is what turns "we have CodeDeploy" into "we have a production deployment system":
- AWS Systems Manager (SSM) Parameter Store parameters for runtime config
- Amazon Simple Notification Service (Amazon SNS) for deploy notifications
- Amazon EventBridge for pipeline state changes
- CloudWatch alarms
When EC2 with CodeDeploy is the right call
EC2 with CodeDeploy is still the right call in a few specific situations. If these apply, I would stay on EC2 and not move to ECS:
- Your app has persistent local state, IPC between processes, or syscall requirements that make containers awkward
- You deploy fewer than about 10 times a day and the 5 to 15 minute CodeDeploy lifecycle overhead is acceptable
- The team owns the OS and runtime environment and wants to keep it that way
- You have compliance or licensing requirements tied to specific machine configurations
- You are migrating a legacy app and containerizing it is a quarter-long project
If you deploy 20 or more times a day and speed matters, containers are better. But for the workloads where EC2 fits, this architecture gives you zero-downtime rolling deploys without the operational overhead of Amazon ECS or Amazon Elastic Kubernetes Service (Amazon EKS).
How the four layers fit together
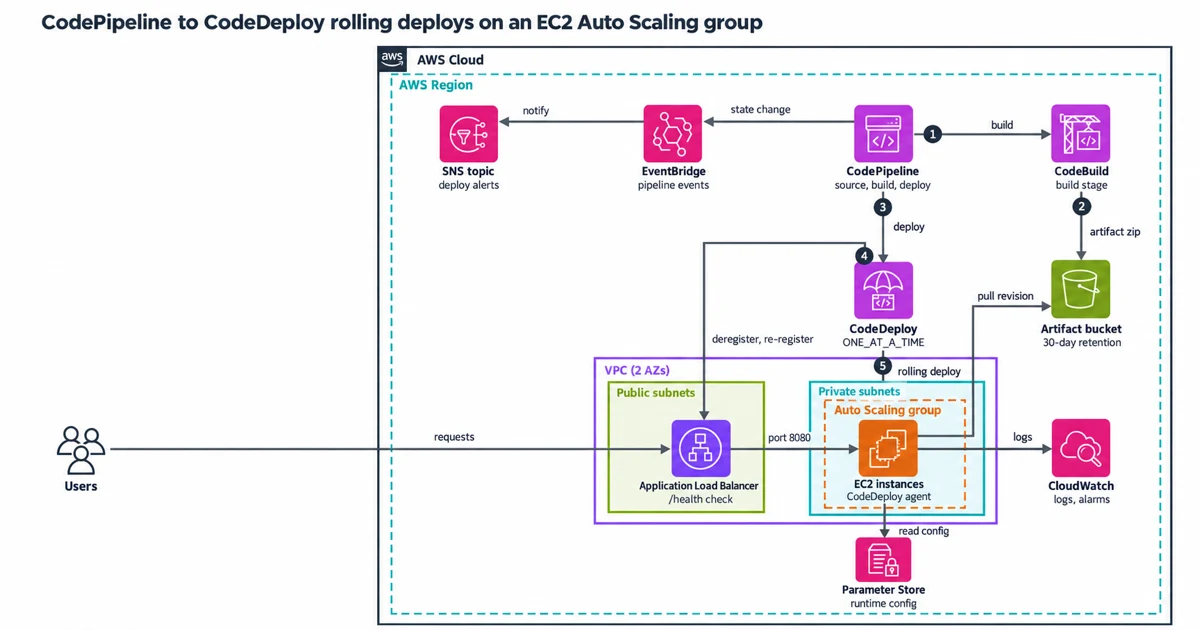
The design has four layers: network, compute, the CI/CD spine and observability. The shape is standard, and the wiring details decide how deploys behave.
Network tier: A custom Amazon Virtual Private Cloud (Amazon VPC) with public and private subnets across 2 Availability Zones (AZs). The internet-facing ALB lives in the public tier. EC2 instances live in the private tier with no direct internet exposure.
The subnet design here follows the same public/private split as the CDK IAM and VPC security-as-code build. If you are unsure how many AZs or what your CIDR blocks should look like, start there.
Compute tier: The Auto Scaling group runs in the private subnets. Instances pull runtime config from SSM Parameter Store, so no secrets are baked into Amazon Machine Images (AMIs) and no environment variables sit in user data. The CodeDeploy agent runs on each instance and polls for deployment instructions.
CI/CD spine: S3 is the artifact store. CodePipeline orchestrates source to build to deploy. CodeBuild handles the build stage. CodeDeploy runs rolling deployments onto the ASG using deployment groups tied to the ASG directly.
Observability: CloudWatch log groups have explicit retention (the cost section explains why), and alarms watch the key signals. EventBridge routes pipeline state change events downstream. SNS handles notifications.
One piece is easy to miss: CodeDeploy needs to know about the ALB. You configure the deployment group with the ALB target group, which tells CodeDeploy to deregister instances from the ALB before installing the new version and re-register after. That is how you get zero-downtime rolling deploys.
Skip this wiring and CodeDeploy deploys while the ALB is still routing traffic to instances being updated. You see a small number of errors that are hard to trace.
Wire the ALB, target group and deployment group in CDK
This sanitized CDK snippet shows the ALB-to-ASG wiring, the part examples often skip:
// ALB → Target Group → ASG wiring
const targetGroup = new elbv2.ApplicationTargetGroup(this, 'AppTargetGroup', {
 vpc,
 port: 8080,
 protocol: elbv2.ApplicationProtocol.HTTP,
 targetType: elbv2.TargetType.INSTANCE,
 healthCheck: {
 path: '/health', // Return 200 only once the app can serve traffic
 healthyThresholdCount: 2,
 unhealthyThresholdCount: 3,
 interval: Duration.seconds(30),
 timeout: Duration.seconds(10),
 },
 deregistrationDelay: Duration.seconds(60), // Give in-flight requests time to drain
});

// ASG registers itself with the target group
asg.attachToApplicationTargetGroup(targetGroup);

// CodeDeploy deployment group knows about the ALB
const deploymentGroup = new codedeploy.ServerDeploymentGroup(this, 'DeploymentGroup', {
 application: codeDeployApp,
 autoScalingGroups: [asg],
 loadBalancer: codedeploy.LoadBalancer.application(targetGroup),
 deploymentConfig: codedeploy.ServerDeploymentConfig.ONE_AT_A_TIME,
 installAgent: true,
});
Three settings in it need care.
The health check path. /health should return HTTP 200 only once the application can serve traffic, after caches and connection pools are warm. Some apps take 30 seconds to warm up. A path that returns 200 too early sends traffic to an instance that is not ready. A check that is too tight during warm-up keeps a ready instance out of service and can fail the deploy. Set healthyThresholdCount: 2 and leave room in the interval.
deregistrationDelay: 300 seconds by default. For most EC2 apps that is five minutes of waiting during every rolling deploy. Drop it to 30 to 60 seconds unless you have long-lived connections.
ONE_AT_A_TIME vs HALF_AT_A_TIME: For smaller fleets, under about 10 instances, ONE_AT_A_TIME is safer during rollouts. For larger fleets HALF_AT_A_TIME is faster but means half your fleet is unavailable during the install phase. Pick based on fleet size and traffic.
This snippet does not cover the AWS Identity and Access Management (IAM) role construction, the AppSpec configuration or the step that suspends ASG scaling processes during deploys. Much of the detail on why deploys break lives in those parts.
Trade-offs you accept with EC2 deploys
Deploy speed vs operational simplicity. CodeDeploy lifecycle hooks (BeforeInstall, AfterInstall, ApplicationStart, ValidateService) add 5 to 15 minutes per rolling deploy. At 10 or more deploys a day that overhead compounds.
Container swaps on ECS are measured in seconds. EC2 CodeDeploy is measured in minutes. That gap is the cost of the model.
S3 artifacts vs container images. Zip-based artifacts are simple and cheap, but you lose layer caching and immutable image semantics. Every deploy re-transfers the full artifact. For small apps it does not matter. For apps carrying 500MB of dependencies, it adds up.
SSM Parameter Store. Standard tier is free up to 10,000 parameters. Cross into advanced tier and it is $0.05 per parameter per month. The part that is harder to spot: teams hit TooManyUpdates during high-frequency deploys when deploy scripts on several instances write the same parameter with PutParameter at once. Reads do not cause it. It surfaces as deploy failures that look like network issues.
Four failure modes and how to prevent each
Start with the one this article opened on: CodeDeploy reports success, ALB shows 502s. This happens when the deployment group is not wired to the target group. Without that wiring, CodeDeploy considers the instance healthy once its lifecycle hooks exit successfully, and the ALB has its own opinion based on the health check. The two are not synchronized.
With the target group in the deployment group, as in the snippet above, CodeDeploy re-registers each instance in its AllowTraffic step and waits up to an hour for it to pass the ALB health check. If it never passes, CodeDeploy moves on or fails the deployment, depending on the deployment configuration. So wire the target group, and make the health check path report real readiness.
Rollback with nothing to roll back to. If your S3 artifact bucket lifecycle policy deletes old versions aggressively, a failed deploy has no previous revision to restore. Set a minimum 30-day retention on the artifact bucket. Do not let a lifecycle policy clean up the one thing CodeDeploy needs to recover.
Scale-in during deploy. The ASG decides to terminate an instance mid-deploy because a scale-in event fired. CodeDeploy reports partial success on a shrinking fleet. The fix is to suspend the ASG Terminate process for the length of the deploy and resume it afterwards, for example with aws autoscaling suspend-processes --scaling-processes Terminate in a pipeline step before the deploy stage. That is a process suspension, not a lifecycle hook. CDK examples often skip this, and it is slow to diagnose because nothing in the deploy logs points at the ASG.
Silent pipeline failures. Without a CloudWatch alarm on FAILED state transitions from your EventBridge rules, a stuck pipeline can go unnoticed for hours. Create the alarm. The Fargate, Aurora and CloudFront build shows how I wire CloudWatch alarms across a whole stack.
Scope the IAM roles and make notifications reliable
IAM is where this architecture is most likely to fail a security audit. CDK does not attach AWSCodeBuildAdminAccess for you. A CodeBuild project it creates gets a new role with inline statements for its logs and report groups, and a server deployment group gets the AWS managed AWSCodeDeployRole policy. The broad grant usually arrives by hand: AWSCodeBuildAdminAccess attached to a CodeBuild role to unblock a build fails least privilege. It usually comes with a plan to tighten it later, and that cleanup rarely happens. The CDK IAM and VPC security-as-code post shows how to scope roles to the actions and resources they actually use.
EC2 instance profiles need SSM access for Parameter Store reads, CloudWatch Logs access for the agent, and S3 access to pull deployment artifacts. They need nothing else.
SNS email subscriptions require manual confirmation. A team automates everything, forgets to click the confirmation link, and finds the deploy notification channel silent during the first real incident. Subscribe an SQS queue or Lambda instead if you want reliable delivery.
What it costs for a five-instance fleet
Monthly numbers for a modest fleet (5 EC2 instances, t3.medium, us-east-1). Treat these as estimates, not quotes:
- EC2 (5x t3.medium On-Demand): roughly $150 to $170/month
- ALB: roughly $20/month base plus data processing charges
- NAT Gateway (private subnet egress): $0.045/hour, about $32.85/month per gateway at 730 hours, plus $0.045/GB processed (VPC pricing, checked 2026-10-18)
- CodePipeline: about $1/month per active pipeline
- CodeBuild: first 100 build minutes/month free, then about $0.005/minute on general1.small
- S3 (artifact storage): under $5/month for most teams
- CloudWatch Logs (default never-expire retention): the surprise line, easily $50 to $200/month for a busy fleet
The CloudWatch Logs line is the one teams miss. Verbose app logs on 5 EC2 instances with no retention policy cost $0.50/GB to ingest and $0.03/GB/month to store, forever.
Set explicit retention on every log group. 30 days is usually right, 90 days at most unless compliance requires more. Do not leave the CloudWatch default, which keeps logs forever.
For a broader look at where AWS spend goes, the AWS cost optimization audit checklist walks through it phase by phase.
Three things I would set up from day one
On a new build of this pattern, I would set up three things from day one.
1. VPC endpoints from day one. Without VPC endpoints, SSM, S3 and CloudWatch Logs calls go out through the NAT Gateway and you pay NAT Gateway egress for traffic that never needed to touch the internet. Gateway endpoints for S3 and DynamoDB are free; interface endpoints are about $7.30/month per AZ. At any real volume that beats NAT data processing.
2. Skip the email SNS subscription. Send notifications to an Amazon Simple Queue Service (Amazon SQS) queue, then an AWS Lambda function, then Slack or PagerDuty. Email subscriptions need manual confirmation, deliver unreliably, and the AWS notification inbox often goes unread. Build the automation from day one.
3. Validate the ALB health check before the first real deploy. It sounds obvious, and it is easy to skip. Hit /health manually from an instance in the private subnet, confirm it returns 200 inside your timeout, then deploy. Do not discover the health check is broken mid-deploy.
Three checks before your next deploy
A reliable deploy pipeline here is mostly a configuration problem. Before your next deploy, do three checks:
- Confirm the ALB health check returns 200 once the app has started, inside the health check timeout.
- Set a 30-day floor on the artifact bucket so rollback always has a target.
- Put a CloudWatch alarm on pipeline
FAILEDtransitions so a stuck deploy cannot hide.
Get the lifecycle hooks right, get the health checks aligned, set your log retention. The rest is wiring.
Sources
Pages were read on 2026-10-18 unless noted.
AWS pricing pages
- Amazon VPC Pricing: NAT Gateway hourly and per-GB charges.
- Elastic Load Balancing pricing: Application Load Balancer hourly charge.
- AWS PrivateLink Pricing: interface endpoint hourly charge per AZ.
- AWS CodePipeline pricing: per active pipeline charge (V1 model).
- AWS CodeBuild Pricing: the free monthly build minutes and the general1.small per-minute rate.
- Amazon CloudWatch Pricing: CloudWatch Logs ingestion and storage charges.
- AWS Systems Manager Pricing: Parameter Store standard and advanced tier charges.
Other AWS documentation
- Gateway endpoints: S3 and DynamoDB gateway endpoints have no additional charge.
- Working with log groups and log streams: log data is stored indefinitely by default until a retention period is set.
- PutParameter: the TooManyUpdates error for concurrent updates to a parameter (read again 2026-10-27).
- Deployment configurations on an EC2/On-Premises compute platform: OneAtATime and HalfAtATime behaviour.
- AppSpec 'hooks' section: the BeforeInstall, AfterInstall, ApplicationStart and ValidateService lifecycle hooks.
- Integrating CodeDeploy with Elastic Load Balancing: deregistering and re-registering instances from the load balancer during an in-place deployment, and waiting up to an hour for each instance to become healthy behind it (read again 2026-10-27).
- Suspend and resume Amazon EC2 Auto Scaling processes: the
Terminateprocess and how to suspend it (read 2026-10-27). - Integrating CodeDeploy with Amazon EC2 Auto Scaling: the race between a scale-in termination and a running deployment (read 2026-10-27).
- class Project (construct) and class ServerDeploymentGroup (construct), AWS CDK API Reference: both create a role by default (read 2026-10-27).
- aws-codebuild project.ts and aws-codedeploy server deployment-group.ts, AWS CDK source: the inline statements on the CodeBuild role and the
AWSCodeDeployRolemanaged policy on the deployment group role (read 2026-10-27). - Target group attributes: the 300-second default deregistration delay.
Next step
Have the same problem on your stack?
Send the architecture, AWS bill concern, deploy pain, or GenAI reliability issue. I'll find the first real bottleneck and propose a small, reversible fix.
FAQ
How do I stop 502 errors during a CodeDeploy deployment behind an ALB?
Configure the CodeDeploy deployment group with the ALB target group, so CodeDeploy deregisters each instance from the ALB before installing the new version and re-registers it after. CodeDeploy then waits for each instance to pass the ALB health check before it moves on, so make the health check path return 200 only once the app can serve traffic.
Why does a CodeDeploy rollback fail with nothing to roll back to?
If the S3 artifact bucket has a lifecycle policy that deletes old versions aggressively, a failed deploy has no previous revision to restore. Set a minimum 30-day retention on the artifact bucket.
What deregistration delay should I use for CodeDeploy rolling deploys on EC2?
The ALB target group default is 300 seconds, which for most EC2 apps adds five minutes of waiting during every rolling deploy. Drop it to 30 to 60 seconds unless you have long-lived connections.
Should I use ONE_AT_A_TIME or HALF_AT_A_TIME for a CodeDeploy deployment group?
For fleets under about 10 instances, ONE_AT_A_TIME is safer during rollouts. HALF_AT_A_TIME is faster for larger fleets, but half the fleet is unavailable during the install phase.
When should I use EC2 with CodeDeploy instead of ECS?
EC2 with CodeDeploy fits apps with persistent local state or syscall needs that make containers awkward, teams deploying fewer than about 10 times a day, and legacy apps where containerizing is a quarter-long project. If you deploy 20 or more times a day and speed matters, containers are better.
Related reading
Rahul Ladumor
Principal Cloud & AI Platform Architect. AWS Professional certified, 5x AWS Community Builder. I work with teams that have real users, real AWS bills, and real production pressure.
About Rahul →