AWS CDK web app deployment: VPC, Fargate, Aurora and CloudFront wired together
AWS CDK web app deployment on ECS Fargate, Aurora and CloudFront: the VPC layout, CDK code, monthly costs and the quiet failures to close before production.
On this page
Your AWS Cloud Development Kit (AWS CDK) stack deploys, the pipeline goes green, and it looks like production. Then an audit finds the database password has not changed in months, because AWS Secrets Manager rotation was failing quietly after a refactor removed a security group rule. This guide is for engineers who already ship CDK stacks and need a web app stack that survives production traffic, failed secret rotation and the monthly bill: Amazon Virtual Private Cloud (Amazon VPC), Amazon Elastic Container Service (Amazon ECS) on AWS Fargate, Amazon Aurora and Amazon CloudFront. You get the CDK code, the trade-offs, a monthly cost table and the failure modes to close first.
Who this is for
If you are an engineer who has shipped CDK stacks before and you know your way around VPCs, this is for you. It skips subnet basics. I assume you know why private subnets exist and why you do not put Amazon RDS in a public one.
Specifically, you are probably in one of these spots:
- You are building a production web app on AWS and the tutorials all stop at "VPC plus Application Load Balancer (ALB) plus Fargate, good luck."
- You inherited a stack that is "basically production-ready" and you want to know what is actually missing.
- You have wired some of these services together before but never all of them in one CDK app, and you want to understand the dependency graph before an incident shows it to you.
Why the demo stack fails quietly in production
Every CDK tutorial hands you the same three services and calls it done. VPC. Fargate. ALB. "You are production-ready." For a demo, you are.
Real production also needs encrypted RDS with credential rotation, a CDN layer that does not leak your Amazon Simple Storage Service (Amazon S3) bucket to the public internet, an auto scaling policy that does not serve degraded traffic during cold starts, and a networking config that does not silently break when someone touches the route tables.
None of these pieces is hard to build. The risk is that most of them fail quietly.
Secrets Manager rotation does not throw an alarm when it fails. It just stops rotating. The old password keeps working, because a failed rotation leaves the database and the current secret version as they were, so nothing pages anyone. You find out at the next audit, or when a rotation fails halfway and breaks every connection (see the failure section).
Then there is cost, and NAT Gateway is the line that most often surprises teams. A NAT Gateway is $0.045/hour, about $32.85/month per gateway at 730 hours, plus $0.045/GB processed (VPC pricing, checked June 2026). Run one per AZ for HA across three AZs and the base is roughly $99/month before you move a single application byte; the $0.045/GB on top is what makes it balloon under real traffic.
Three NAT Gateways can sit on the bill for months before anyone notices the line. The base alone is real money, and the per-GB charge is the part that grows without anyone watching.
So the hard part of this stack is the wiring between services. Every dependency edge has to be owned explicitly in code: VPC endpoint routes, AWS Key Management Service (AWS KMS) key policies and security group rules. If it is not in code, it drifts.
When this stack is the right choice
This stack is the right call when you have containerized workloads you do not want to manage Amazon EC2 for, a relational data model you are not rewriting soon, variable traffic that needs auto scaling, and a security posture that requires encryption at rest and secret rotation.
If you have three users and a startup budget, Aurora provisioned at roughly $150 to $200/month minimum is the wrong choice right now. Look at Aurora Serverless v2, or run RDS Single-AZ until you have real traffic. This stack is for when you are past "prove the idea" and you need the thing to work under load, under audits, and under on-call pressure.
One more thing: if you are not ready to own the operational surface this creates, wait. The Amazon EventBridge global endpoint failover in this stack is useful, and dangerous if you do not understand what it alarms on. More on that in the failure section.
How the layers fit together
Here is the stack, layer by layer.
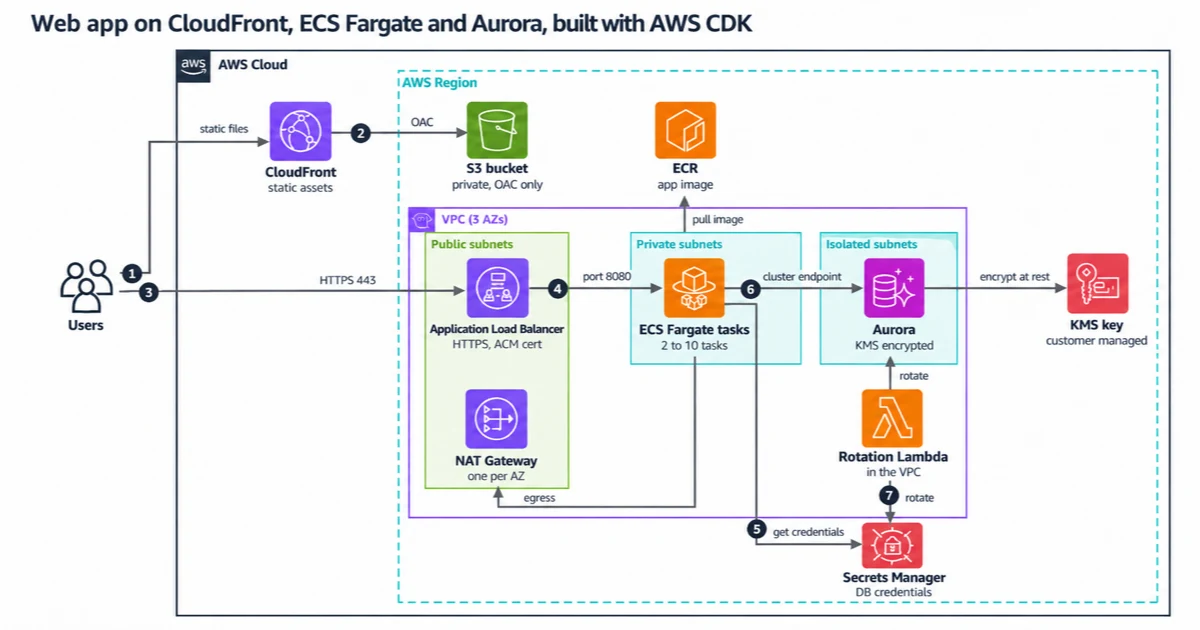
At the bottom: a custom VPC with three subnet tiers. Public subnets get the ALB and NAT Gateways. Private subnets get the Fargate tasks. Isolated subnets, no internet route at all, get Aurora.
The isolated tier is a network control. Even if someone misconfigures a security group, there is no route for Aurora to call home, because the VPC itself enforces the isolation.
Above that: an Application Load Balancer in the public subnets, HTTPS terminated with an AWS Certificate Manager (ACM) certificate, forwarding to ECS Fargate tasks that pull images from Amazon Elastic Container Registry (Amazon ECR). The Fargate tasks live in private subnets. They reach out through NAT, but nothing external reaches them directly.
Aurora sits in those isolated subnets with KMS encryption. Credentials get vended through Secrets Manager, with rotation configured through an AWS Lambda rotator in the same VPC. S3 plus CloudFront handles static asset delivery with origin access control (OAC, not the old origin access identity pattern), so S3 is never publicly accessible.
Auto Scaling watches ALB RequestCountPerTarget and adjusts the Fargate task count. Amazon CloudWatch collects logs and alarms across the stack. The last piece is an EventBridge global endpoint with Amazon Route 53 health checks for cross-region failover.
Most CDK examples skip this. It fits a stack that is building toward multi-region active-active, and a later section covers when a simpler failover is enough.
VPC endpoint wiring in CDK gets a deeper look in the CDK IAM and VPC security-as-code post.
Build the VPC, Fargate service and scaling in CDK
Here is the shape of the CDK code. I walk through the Fargate plus ALB wiring since that is the core of the stack; the Aurora setup and EventBridge failover logic deserve their own context because the failure modes are involved.
The VPC construct goes first. Always. Everything depends on it:
const vpc = new ec2.Vpc(this, 'AppVpc', {
 maxAzs: 3,
 natGateways: 3, // one per AZ - yes this costs money, yes it's worth it
 subnetConfiguration: [
 { name: 'Public', subnetType: ec2.SubnetType.PUBLIC, cidrMask: 24 },
 { name: 'Private', subnetType: ec2.SubnetType.PRIVATE_WITH_EGRESS, cidrMask: 24 },
 { name: 'Isolated', subnetType: ec2.SubnetType.PRIVATE_ISOLATED, cidrMask: 24 },
 ],
});
Then the ECS cluster and Fargate service:
const cluster = new ecs.Cluster(this, 'AppCluster', { vpc });

const taskDef = new ecs.FargateTaskDefinition(this, 'AppTask', {
 memoryLimitMiB: 1024,
 cpu: 512,
});

taskDef.addContainer('AppContainer', {
 image: ecs.ContainerImage.fromEcrRepository(repo, 'latest'),
 portMappings: [{ containerPort: 8080 }],
 logging: ecs.LogDrivers.awsLogs({ streamPrefix: 'app' }),
});

const service = new ecs_patterns.ApplicationLoadBalancedFargateService(this, 'AppService', {
 cluster,
 taskDefinition: taskDef,
 publicLoadBalancer: true,
 listenerPort: 443,
 certificate: acmCert,
 taskSubnets: { subnetType: ec2.SubnetType.PRIVATE_WITH_EGRESS },
});
And the auto scaling policy:
const scaling = service.service.autoScaleTaskCount({ maxCapacity: 10, minCapacity: 2 });
scaling.scaleOnRequestCount('RequestScaling', {
 requestsPerTarget: 1000,
 targetGroup: service.targetGroup,
});
That requestsPerTarget number is the one to watch. Too low and you spin up tasks constantly. Too high and you are degraded before scaling kicks in.
Start conservative, watch your metrics for two weeks, then tune. Over-tuning in either direction can cost you a deploy window.
Three cost trade-offs to decide
NAT Gateway vs VPC endpoints. Three NAT Gateways for HA is roughly $99/month base before data transfer, and the $0.045/GB on top is what actually scales. You can cut a lot of that by using VPC Interface Endpoints for ECR, Secrets Manager, and CloudWatch Logs, the services your Fargate tasks actually need. The trade-off is construct complexity; each endpoint needs its own security group and DNS config. If you are doing this from scratch, the per-endpoint cost math in the S3, EventBridge and Lambda cost breakdown is where I would start.
Aurora provisioned vs Serverless v2. The provisioned Aurora cluster here runs roughly $150 to $200/month minimum regardless of whether you have one user or ten thousand. That is the right call for consistent baseline traffic; the performance predictability is real. If your traffic is spiky or you are early stage, Aurora Serverless v2 cuts idle cost toward zero. Treat these as estimates and check current RDS pricing for your instance class and region.
Fargate vs EC2. Fargate costs roughly 20 to 30 percent more per vCPU-hour than equivalent EC2. At 5 tasks you do not care. At 50 tasks running 24/7 it is a different conversation.
Skipping AMI patching, ECS agent management, and instance right-sizing is worth the premium at low task counts. At high counts, run the math.
Three ways this stack breaks quietly
The Secrets Manager rotation failure deserves the most time, because nothing tells you it happened.
Rotation requires a Lambda rotator deployed into the same VPC as your Aurora cluster, with a route to the RDS endpoint and a security group rule allowing the connection. If that security group rule gets removed during a refactor, maybe someone was cleaning up security groups and did not realize the rule was load-bearing, rotation silently fails.
Nothing alarms. Your CloudWatch dashboard looks fine. Your tasks are healthy, because the credential does not expire: Aurora keeps accepting the old password, and the AWSCURRENT version of the secret still holds it. The damage is a password that never rotates, which an audit finds months later.
The outage case is a rotation that fails halfway. The rotation function changes the database password in its setSecret step and only moves AWSCURRENT to the new value in finishSecret. If it fails between the two, the database has the new password, the secret still hands out the old one, and every new connection from every task fails at once.
The EventBridge global endpoint has a quiet failure mode too. The health alarm uses Invocations as its signal, with treatMissingData: NOT_BREACHING. So if your application legitimately goes quiet, say an overnight maintenance window with no events, the alarm treats missing data as healthy.
That is the right default for a consistently event-driven system. But for low-volume applications you can go days without an invocation legitimately, and then when something actually breaks the alarm does not fire because it is used to seeing nothing. You need a dead-man's-switch pattern here, or a more precise metric.
Cold start lag during scaling spikes is the third. ALB RequestCountPerTarget is reactive: you are already under load before the scaling policy sees it. A Fargate task takes 30 to 60 seconds to start.
That gap means your first burst hits your existing task count, possibly at full saturation. Predictive scaling or a pre-warm strategy helps, but this is inherent to reactive scaling.
For a deeper look at these patterns, multi-region disaster recovery on AWS covers the DR patterns and how to set RTO and RPO per workload.
Security settings that are not optional
Three settings in this stack need explicit care.
A KMS customer managed key (CMK) for Aurora adds about $1/month per key plus $0.03 per 10,000 API calls. The cost is small; the concern is key policy drift. If the Lambda rotation function's kms:Decrypt permission gets removed from the key policy, again, a quiet refactor drops a statement someone did not recognize, rotation breaks, and you do not find out until an audit, or until a half-finished rotation leaves the database and the secret out of step.
S3 with OAC (origin access control) means your bucket policy only permits CloudFront's service principal, not the deprecated OAI ARN pattern. This is the right setup. If you see a tutorial using OriginAccessIdentity instead of OriginAccessControl, that is the old way. OAC is more secure and works with SSE-S3 and SSE-KMS buckets.
For Secrets Manager rotation specifically, make sure you have a Secrets Manager rotation failure alarm in place. AWS does not give you one by default. You have to explicitly alarm on rotation failure events in CloudWatch. Most teams do not add this until after the first incident.
What the stack costs per month
These are monthly estimates for us-east-1 at baseline load:
| Service | Monthly estimate |
|---|---|
| NAT Gateway x3 (~$33 base each) + data | ~$99 base, plus $0.045/GB |
| Aurora Provisioned (db.t3.medium) | ~$150-200 |
| Fargate (2 tasks baseline) | ~$30-50 |
| CloudFront + S3 | ~$5-20 |
| ALB | ~$20 |
| KMS CMK | ~$1-2 |
| Secrets Manager | ~$1 |
| Total baseline | ~$306-392/month plus NAT data transfer |
Two levers stand out. NAT is the first: replace two of the three NAT Gateways with VPC endpoints for ECR, Secrets Manager, and CloudWatch (the three services Fargate actually needs) and you cut both base gateway hours and the per-GB data processing. Whether that is worth the construct complexity depends on your traffic volume.
Aurora is the other. If your traffic profile justifies Serverless v2, that $150 to $200 baseline drops toward zero at idle and scales with usage.
What I would do from day one
Three things.
First, VPC endpoints from day one. I would set up Interface Endpoints for ECR API, ECR DKR, Secrets Manager, and CloudWatch Logs before deploying a single Fargate task. Endpoints cost about $7.30/month per AZ; four endpoints across three AZs is roughly $88/month, cheaper than three NAT Gateways once data processing is in play, and it removes NAT as a single-bandwidth bottleneck for high-throughput workloads.
Second, add an explicit CloudWatch alarm on Secrets Manager rotation failure events on day one. Do not leave it for later. The failure mode is too quiet and too catastrophic to leave unmonitored.
Third, decide whether you actually need the EventBridge global endpoint before adding it. It is sophisticated and it adds real operational complexity, especially the CDK bootstrap ordering for cross-region stacks. If you are not actively building toward multi-region active-active, a Route 53 health check plus failover record might be all you need, and it is far simpler to reason about.
Deployment failures to plan for
Three things can go wrong while you deploy.
First, Fargate task health checks. If your container takes longer than the ALB health check grace period to start serving, the task gets killed and replaced in a loop. A common case is a JVM app that needs 45 seconds to warm up against a grace period set to 30. The fix is simple: match the grace period to your actual startup time, not the default.
Second, Aurora failover during a deploy. If Aurora fails over while Fargate is rolling out a new task definition, you get a window where new tasks connect to the old writer endpoint that is now a reader. Connection errors spike, the circuit breaker trips, and your deploy looks failed even though the code is fine. The mitigation is a retry-aware connection using the cluster endpoint, not the instance endpoint.
Third, CloudFront cache invalidation timing. You push a new version, Fargate picks it up, CloudFront still serves the old version from cache. Users see stale content and file bugs. The fix: invalidate on deploy (adds 30 to 60 seconds and costs money) or use versioned asset paths so old and new coexist.
What to check before you ship
Wiring services together in CDK means you own every dependency edge explicitly. That is the value of doing it in code, and also the trap. When an edge breaks, such as a security group rule, a key policy statement or a route table entry, it breaks quietly, and you find out at an audit or in an incident, not at deploy time. Before you ship, add the Secrets Manager rotation alarm, confirm your Fargate health check grace period matches real startup time, and trace where your NAT traffic is actually going. Those three close most of the quiet gaps in this stack.
Sources
Pages were read on 2026-10-18 unless noted.
AWS pricing pages
- Amazon VPC Pricing: NAT Gateway hourly and per-GB charges.
- AWS PrivateLink Pricing: interface endpoint hourly and per-GB charges.
- AWS Key Management Service Pricing: per-key and per-request KMS charges.
- AWS Fargate Pricing: per-vCPU and per-GB Fargate task charges.
- Elastic Load Balancing pricing: Application Load Balancer hourly and LCU charges.
- AWS Secrets Manager Pricing: per-secret and per-API-call charges.
- Amazon CloudFront Pricing: data transfer and request charges, and the free monthly invalidation allowance.
- Amazon Aurora Pricing: Aurora Serverless v2 ACU billing, and provisioned storage and I/O charges.
Other AWS documentation
- Restricting access to an Amazon Simple Storage Service origin: origin access control (OAC) recommended over the legacy origin access identity (OAI), and OAC support for SSE-KMS.
- Lambda rotation functions, AWS Secrets Manager User Guide: the four rotation steps, with
setSecretchanging the database credential andfinishSecretmoving theAWSCURRENTlabel (read 2026-10-27). - Rotation by Lambda function, AWS Secrets Manager User Guide: a failed step makes Secrets Manager retry the whole rotation during the rotation window (read 2026-10-27).
Next step
Have the same problem on your stack?
Send the architecture, AWS bill concern, deploy pain, or GenAI reliability issue. I'll find the first real bottleneck and propose a small, reversible fix.
FAQ
How much does a NAT Gateway cost per month?
A NAT Gateway is $0.045 per hour, about $32.85 per month at 730 hours, plus $0.045 per GB processed. Running one per Availability Zone across three AZs costs roughly $99 per month before any application data moves.
Should I use Aurora Serverless v2 or provisioned Aurora?
A provisioned Aurora cluster in this stack runs roughly $150 to $200 per month minimum, whatever the traffic, which suits a consistent baseline load. For spiky or early-stage traffic, Aurora Serverless v2 cuts idle cost toward zero. Check current pricing for your instance class and Region.
Why does Secrets Manager rotation fail silently?
Rotation runs through a Lambda rotator in the same VPC as the Aurora cluster, which needs a route to the database endpoint, a security group rule allowing the connection and kms:Decrypt on the key. If a refactor removes that rule or that key policy statement, rotation stops without an alarm, because AWS does not give you a rotation failure alarm by default.
Why do my ECS Fargate tasks keep getting replaced behind an ALB?
If the container takes longer to start serving than the ALB health check grace period, the task is killed and replaced in a loop. A JVM app that needs 45 seconds to warm up against a 30-second grace period is a typical case. Set the grace period to your real startup time.
Should I use CloudFront OAC or OAI for an S3 origin?
Use origin access control (OAC), not the older origin access identity (OAI) pattern. With OAC the bucket policy permits only the CloudFront service principal, and it works with SSE-S3 and SSE-KMS buckets.
Related reading
Rahul Ladumor
Principal Cloud & AI Platform Architect. AWS Professional certified, 5x AWS Community Builder. I work with teams that have real users, real AWS bills, and real production pressure.
About Rahul →