AWS DataSync, DMS and Step Functions in CDK: a multi-environment migration pipeline that does not fail silently
DataSync, DMS and Glue migrations run from one Step Functions workflow in CDK, with a pre-flight Lambda check that fails a bad run before any data moves.
On this page
A migration runs for 45 minutes, reports success and writes incomplete data to production. The AWS Database Migration Service (AWS DMS) replication instance was stopped three days earlier to save money, nobody restarted it, and the pipeline never checked.
This is for platform engineers who run AWS DataSync, AWS DMS, AWS Glue and Amazon OpenSearch Service under one AWS Step Functions workflow in an AWS Cloud Development Kit (AWS CDK) stack. You get the orchestration pattern, the places it fails silently, and the pre-flight check I would build first, so the pipeline confirms every downstream service is ready before it moves a byte.
Who this pipeline is for
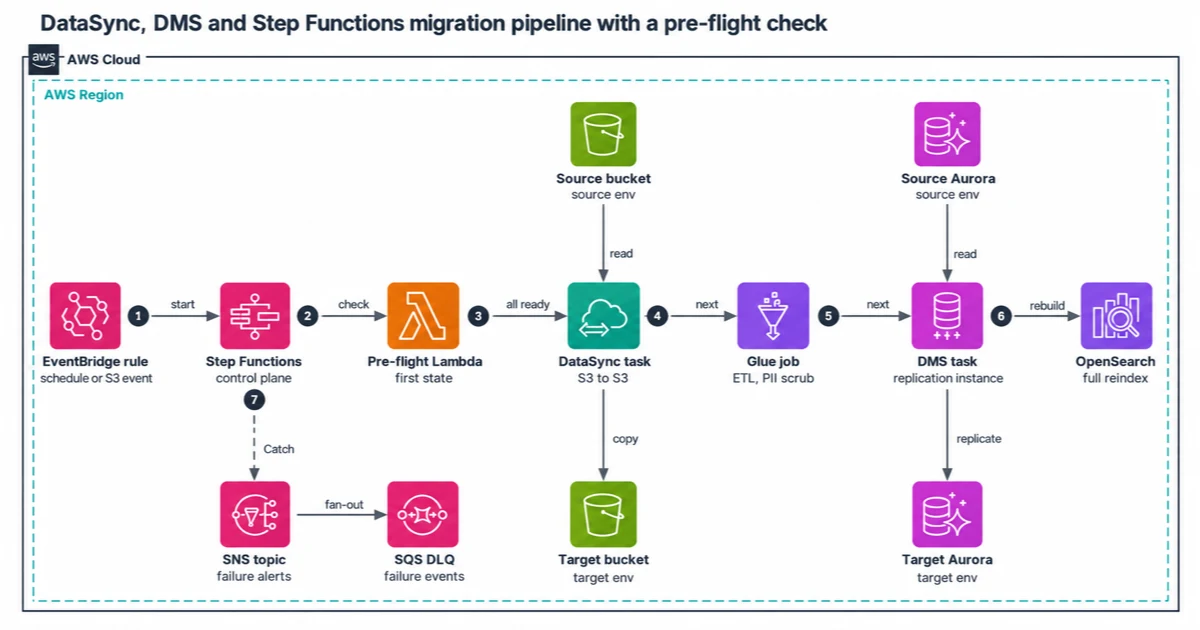
If you are comfortable with CDK TypeScript and have run at least one of DataSync, DMS, or Step Functions in production, this is for you. It skips the "what is DMS" basics and assumes you know what a replication instance is, you have seen a Step Functions state machine, and your question is how to wire all of this together in one CDK stack so it holds up on migration night.
You are probably building a platform-team tool for environment promotion (dev to staging to prod), or you inherited a pile of cron jobs and ad-hoc scripts that mostly work and need to replace them with something auditable. Either way, the high-level idea (five services, one state machine) is the easy part. The useful part is operational: where the naive version fails silently, and what to build so it fails loudly and early instead.
Why scripts and cron jobs fail as a migration pipeline
Moving data between AWS environments sounds like solved territory. Amazon S3 has replication, Amazon Aurora has DMS, and OpenSearch is where it gets complicated. The hard part is the orchestration layer that ties them together.
Teams say "we have a script for that." What they actually have is a cron job that kicks off a DataSync task, a separate AWS Lambda function watching for DMS replication to finish, a third thing rebuilding the OpenSearch index, and a Slack notification that may or may not fire when something goes wrong.
This works on migration run #1. Run #2, someone changed a security group. Run #3, the DMS instance was stopped to save money and nobody restarted it. Run #4, Glue reprocessed the full dataset because nobody configured bookmarks, and now there are duplicate records in Aurora.
What fixes it is a single orchestrator with real failure semantics, in place of the scripts.
Step Functions gives you that, and it also gives you a new problem: it has no idea whether DataSync, DMS, Glue, or OpenSearch are actually ready before it starts. It fires the first state and hopes. More on that in the failure section.
The pipeline here handles three migration targets across environments: S3 buckets (bulk file data), Aurora (relational) and OpenSearch indexes. It runs on a schedule or on demand, with failure notifications that actually reach a human.
How the CDK stack wires each service
The core breaks into four services doing the work, one orchestrator running the show, and one pre-flight layer the naive version is missing entirely.
DataSync handles S3-to-S3. The stack provisions a DataSync task with source and destination location resources pointing at your environment-specific buckets. DataSync beats S3 Cross-Region Replication here because it gives task-level control: throttle bandwidth, filter by prefix, and get a task-level completion event Step Functions can wait on.
The cost is $0.0125/GB (DataSync pricing, checked 2026-10-18), which for a 500 GB monthly workload is $6.25 in DataSync charges on top of S3 request costs. That sounds harmless until you sync the same 500 GB five times because someone triggered migration runs manually to check if it worked, and those five runs billed real money while fixing nothing.
DMS handles Aurora migration: one replication instance (backed by Amazon EC2), source and target endpoints, a replication task. The persistent replication instance is the expensive part, roughly $70 to $150/month depending on instance class (estimate, varies by class and region), running 24/7 whether or not a migration is happening. There are ways around that with a start/stop Lambda hook the stack provisions alongside DMS. For Aurora cost trade-offs more broadly, the AWS cost optimization audit checklist covers right-sizing databases and the rest of the bill.
Glue does ETL transformation in the middle: scrubbing PII before it lands in dev, transforming schema versions, filtering records. Glue jobs sit between DataSync completing and DMS starting, which introduces 2 to 10 minutes of cold-start latency per run.
That is fine for nightly cadences. It is a problem if you expect near-real-time environment sync, because this pipeline will not give you that.
Step Functions is the control plane. The partial CDK snippet below shows the core orchestration chain. It is intentionally incomplete: it shows the pattern, without the rest of the deployable stack.
// Illustrative only - not the full stack
const datasynctaskState = new tasks.CallAwsService(this, 'StartDataSyncTask', {
 service: 'datasync',
 action: 'startTaskExecution',
 parameters: {
 TaskArn: dataSyncTask.taskArn,
 },
 iamResources: [dataSyncTask.taskArn],
}).addCatch(migrationFailureHandler, {
 errors: ['States.ALL'],
 resultPath: '$.errorInfo',
});

const dmsTaskState = new tasks.CallAwsService(this, 'StartDMSReplication', {
 service: 'databasemigration',
 action: 'startReplicationTask',
 parameters: {
 ReplicationTaskArn: replicationTask.ref,
 StartReplicationTaskType: 'start-replication',
 },
 iamResources: ['*'],
}).addCatch(migrationFailureHandler, {
 errors: ['States.ALL'],
 resultPath: '$.errorInfo',
});

// Chain: DataSync -> Glue -> DMS -> OpenSearch rebuild
const definition = datasynctaskState
 .next(glueJobState)
 .next(dmsTaskState)
 .next(openSearchRebuildState);
The addCatch on every state is the part most people skip the first time. Without it, the first service error fails the whole execution. It ends in a Failed state, the failure handler never runs, so its notification and cleanup never happen, and your data is in an unknown condition. For where Step Functions fits in a wider move, migrating legacy infrastructure to AWS serverless covers the general patterns.
There is one more gap in this snippet. startTaskExecution and startReplicationTask return as soon as the job starts, not when it finishes. As written, Glue starts while DataSync is still copying, and the OpenSearch rebuild starts while DMS is still loading. AWS SDK integrations in Step Functions do not support the Run a Job (.sync) pattern, so for DataSync and DMS you build a wait loop: a Wait state, a describe call (DescribeTaskExecution or DescribeReplicationTasks) and a Choice state that loops until the status is final. AWS Glue has an optimized integration that supports .sync, so tasks.GlueStartJobRun with integrationPattern: sfn.IntegrationPattern.RUN_JOB waits for the job run to finish. The default is request and response, which does not wait. I have not tested these loops as part of this stack, so treat them as the pattern, not finished code.
Amazon EventBridge wires the trigger layer. Two modes: scheduled (nightly, a cron expression in the CDK rule) and event-based (S3 ObjectCreated events on prefixes that indicate a source refresh). The S3, EventBridge and Lambda trigger post has the rule structures if you need them.
Decide whether you need this stack
Before you commit to this stack, find your scenario in this table.
| Scenario | Recommendation |
|---|---|
| S3 sync only, same region | Skip DataSync, use S3 Batch Operations |
| < 50 GB migrations, no relational data | Lambda-based sync is cheaper and simpler |
| Need CDC (change data capture) from Aurora | DMS CDC mode, which this stack supports |
| Near-real-time sync required (< 5 min lag) | This stack is wrong. Look at DMS CDC + direct triggers |
| Heterogeneous sources (S3 + Aurora + OpenSearch) | This stack is the right call |
| Budget under $100/month total | Stop DMS instance between runs |
| Compliance audit requirement | Step Functions execution history is your audit log |
| Team has no CDK experience | Terraform version might be easier to maintain |
The two questions that decide it: do you have at least three distinct migration targets (S3, relational, search), and is your migration cadence daily or less frequent? If both answers are yes, this stack makes sense. If either is no, you are overbuilding.
Where the pipeline fails silently, and how to catch it
The pre-flight problem. The biggest gap in the naive version is that Step Functions starts the state machine with no idea whether its downstream services are ready.
DMS replication instance stopped? The state machine starts, calls StartReplicationTask, gets an InvalidResourceStateFault, hits the Catch block, routes to the failure handler. Best case you get paged. Worst case, if the Catch is not wired correctly, it silently marks the execution failed and nothing moves.
The fix is a pre-flight Lambda function as the first state. I would call it the most important architectural decision in the whole stack.
Before a single byte moves, it checks: is the DMS replication instance available? Is the DataSync task not already running? Is the Glue cluster warm, or the cold-start time within SLA? Is OpenSearch cluster health green?
If any fail, the state machine fails fast, before the 45-minute timer starts, before partial data lands anywhere. You trade 30 seconds of pre-flight for not having to manually clean up a 45-minute partial migration.
DataSync partial failures. DataSync task-level status can be SUCCESS while individual file transfers failed on specific S3 prefixes due to permission issues. Step Functions sees the task succeed. Your data is incomplete.
The only way to catch this is parsing the DataSync task execution report, which is written to an S3 bucket you have to configure explicitly. Add a Lambda that reads that report as a verification state after DataSync completes.
Glue bookmark misconfiguration. Without Glue job bookmarks, every run reprocesses the full dataset. For a 500 GB workload with DMS running concurrently, that means duplicate records in Aurora.
Bookmarks are off by default, and turning them on requires understanding your job's input data structure. This is pipeline-specific, not a one-liner.
VPC networking breaks silently. DMS replication instances and DataSync agents live inside your Amazon Virtual Private Cloud (Amazon VPC). Any route table change, security group tightening, or NAT Gateway swap can break connectivity without triggering an alarm until the state machine actually tries to run.
There is no built-in pre-check, which is another argument for the pre-flight Lambda: a connectivity probe from inside the VPC before execution starts. See the CDK IAM and VPC security-as-code build for the VPC and security group patterns that keep this from happening.
The OpenSearch full reindex problem. Every run triggers a full reindex, not incremental, which is fine for typical environment-promotion cadences. But if the source OpenSearch cluster is unavailable mid-migration, for example during a rolling restart or after a bad deployment, the reindex hangs, Step Functions waits, and the whole pipeline stalls. There is no partial-write protection on the target index.
What the on-call engineer needs to know
A few things I would tell the on-call engineer inheriting this stack.
First, your audit trail is the Step Functions execution history. Every state transition, every input and output, every Catch trigger is logged. Before you look anywhere else during an incident, pull the execution ARN and read the event history in order. It tells you exactly which state failed and what the error was.
Second, the DMS replication instance is your most expensive always-on resource, so it is the first place I would look for waste. If migrations run nightly, there is no reason it runs 24/7. The start/stop Lambda hooks can take DMS from about $150/month to roughly $15 to $20/month if migrations complete in 2 to 3 hours nightly. That is around $130/month back per instance (the $150 you were paying minus the ~$20 you still pay), which makes it worth doing from the start.
Third, wire Amazon Simple Queue Service (Amazon SQS) dead-letter queue (DLQ) processing before you go live. Amazon Simple Notification Service (Amazon SNS) failure fan-out to SQS is only useful if something reads the DLQ. An unprocessed DLQ holds failure events that nobody reads. Add a Lambda-based DLQ processor that escalates to PagerDuty after N messages accumulate without resolution.
Fourth, test your pre-flight Lambda against every failure mode before the first production migration. Stop the DMS instance, run the state machine, confirm it fails in state 1, not state 3. Revoke an IAM permission, run again, confirm the pre-flight catches it. This step is easy to skip because "it works in staging," and staging has a permanently running DMS instance.
Build the pre-flight check first
My view: the architecture is sound. Step Functions as a unified control plane across DataSync, DMS, Glue, and OpenSearch is the right call for heterogeneous migration workloads, because it gives you one execution history, one place to check audit state and one failure model. For CDK TypeScript multi-service pipeline patterns more broadly, the CDK CodeDeploy and Auto Scaling pipeline post has context.
But the naive version, with Step Functions coordinating four services and no pre-flight check, no DataSync report validation and no Glue bookmark configuration, still fails silently. The orchestration design holds up. The weak point is the assumption that an orchestrator knows whether its services are ready, and it does not.
Build the pre-flight Lambda first. Before you wire DataSync, before you configure DMS, write the Lambda that checks whether every downstream service is in a runnable state, and make it the first state in every environment's machine. It is what stands between you and the migration that runs for 45 minutes and writes incomplete data because someone stopped the DMS instance three days ago and forgot to restart it.
Sources
Pages were read on 2026-10-18 unless noted.
AWS pricing pages
- AWS DataSync pricing: the per-GB data-transfer charge in Basic mode.
- AWS Database Migration Service Pricing: replication instance charges, used only to frame the cost estimate.
Other AWS documentation
- Configure how much bandwidth your DataSync task uses: per-task bandwidth throttling.
- Filtering data transferred by AWS DataSync: include and exclude filters by prefix.
- Monitoring your file transfers using DataSync task reports: per-item transfer status, so a task can report SUCCESS while individual files fail.
- TaskReportConfig: the S3 bucket destination you configure for task reports.
- Performing large-scale batch operations on Amazon S3 objects: S3 Batch Operations for same-region object copies.
- Tracking processed data using job bookmarks: job bookmarks are disabled by default.
- StartReplicationTask: the InvalidResourceStateFault error when the replication instance is not available.
- Error handling in Step Functions: the States.ALL catch-all error matcher, and an unhandled error failing the entire execution by default (read again 2026-10-27).
- Discover service integration patterns in Step Functions: Request Response moves to the next state as soon as the call returns, and AWS SDK integrations do not support Run a Job (.sync) (read 2026-10-27).
- Start an AWS Glue job with Step Functions: the optimized Glue integration supports Run a Job (.sync) (read 2026-10-27).
- What is Step Functions?: Standard workflows show execution history and are auditable.
Next step
Have the same problem on your stack?
Send the architecture, AWS bill concern, deploy pain, or GenAI reliability issue. I'll find the first real bottleneck and propose a small, reversible fix.
FAQ
How do I orchestrate DataSync, DMS and Glue with Step Functions?
Chain a DataSync task, a Glue job, a DMS replication task and an OpenSearch rebuild in one Step Functions state machine, with addCatch on every state routing errors to a failure handler. The DataSync and DMS start calls return before the job finishes, so add a wait loop after each one, and run Glue with the .sync integration. Make a pre-flight Lambda function the first state, so the run fails fast when a downstream service is not ready.
What happens if the DMS replication instance is stopped when StartReplicationTask runs?
The call returns an InvalidResourceStateFault. With a Catch block on that state, Step Functions routes the error to the failure handler. A pre-flight check that the replication instance is available catches this before any data moves.
Can a DataSync task show SUCCESS when some files failed to transfer?
Yes. Task-level status can be SUCCESS while individual file transfers failed on specific S3 prefixes, for example because of permission issues. To catch it, write the task report to an S3 bucket you configure and add a Lambda verification state that reads the report after DataSync completes.
How do I reduce the cost of an AWS DMS replication instance?
If migrations run nightly, stop the replication instance between runs with start/stop Lambda hooks. When migrations complete in 2 to 3 hours nightly, that takes DMS from about $150/month to roughly $15 to $20/month, an estimate that varies by instance class and Region.
Are AWS Glue job bookmarks enabled by default?
No, Glue job bookmarks are off by default. Without them, every run reprocesses the full dataset, which with DMS running concurrently means duplicate records in Aurora.
Related reading
Rahul Ladumor
Principal Cloud & AI Platform Architect. AWS Professional certified, 5x AWS Community Builder. I work with teams that have real users, real AWS bills, and real production pressure.
About Rahul →